Feb 2, 2025
Alibaba Launches Qwen2.5-Max: A Game-Changer in AI, Beats DeepSeek-V3?
Qwen2.5-Max is a high-performance Mixture-of-Experts (MoE) language model designed for developers and researchers. It offers efficient scaling, strong benchmarking results, and superior adaptability using techniques like SFT and RLHF. Competing with top models like GPT-4o and DeepSeek V3, it powers AI applications, coding tasks, and human preference evaluations.
- Generative AI

Qwen2.5-Max, a large-scale Mixture-of-Expert (MoE) model
Qwen2.5-Max is a powerful Mixture-of-Experts (MoE) language model designed for developers and researchers who need efficient performance without sacrificing capabilities. It competes strongly with both proprietary and open-weight large language models (LLMs) and is built on the latest advancements in MoE architectures, especially those introduced after DeepSeek V3.
Key Uses of Qwen2.5-Max
Chat and Conversational AI: Qwen2.5-Max powers interactive applications like Qwen Chat, allowing users to engage in dynamic conversations and access various features such as artifact exploration and search capabilities.
APIs for Developers: The model is available through the Alibaba Cloud API, enabling developers to integrate Qwen2.5-Max into custom applications or platforms.
Benchmarking and Performance Evaluation: Qwen2.5-Max excels in evaluating AI capabilities in areas such as general capabilities, coding (LiveCodeBench), and human preferences (Arena-Hard).
Innovations of Qwen2.5-Max Compared to Other Models
Scaling and Performance: Qwen2.5-Max demonstrates significant advantages in scaling, both in terms of data and model complexity. It has been pre-trained on a massive dataset and post-trained using techniques such as Supervised Fine-Tuning (SFT) and Reinforcement Learning from Human Feedback (RLHF), making it more adaptable to user needs. This combination of training methods allows the model to handle complex tasks and improve over time with real-world feedback.
Mixture-of-Experts vs. Dense Models: Unlike large dense models like GPT-4o, Qwen2.5-Max leverages the MoE architecture, where only a portion of the model is activated for any given task. This helps achieve better performance while managing computational resources more efficiently.
State-of-the-Art Performance: In direct benchmarks, Qwen2.5-Max outperforms models like DeepSeek V3 and shows competitive results against top models such as GPT-4o and Claude-3.5-Sonnet across tasks like knowledge assessment (MMLU-Pro), coding (LiveCodeBench), and human preference matching (Arena-Hard).
Scaling Data and Model Size: Qwen2.5-Max model improves its performance, reasoning ability, and intelligence by increasing the size of its architecture and utilizing a large volume of training data. This approach is designed to bring the model's capabilities to the level of human intelligence and even beyond.
Future Directions
Qwen2.5-Max is part of ongoing efforts to enhance large language models by increasing data, expanding model size, and using advanced training methods like RLHF. Future versions aim to improve even more in reasoning and problem-solving, with the potential to exceed human cognitive abilities.
Summary
Qwen2.5-Max is a powerful Mixture-of-Experts (MoE) language model designed for developers and researchers who need efficient performance without sacrificing capabilities. It competes strongly with both proprietary and open-weight large language models (LLMs) and is built on the latest advancements in MoE architectures, especially those introduced after DeepSeek V3.
More from the newsroom
Google DeepMind Study Reveals Emerging Risks in Multi-Agent AI Systems
As AI agents increasingly communicate and collaborate autonomously, new research from Google DeepMind reveals how these interactions can lead to unexpected coordination, cheating, and whistleblowing—raising important questions about AI safety and oversight.
Artificial IntelligenceAI ResearchMachine LearningRead more
Florida State University to Host 2026 Artificial Intelligence and Machine Learning Expo (AIMLX26)
Florida State University’s AIMLX26 brings together OpenAI, MIT, and leading researchers to explore the future of Agentic AI and real-world machine learning innovation.
Artificial IntelligenceMachine LearningAI ResearchRead more
GPT-4.5 is here! Discover its game-changing AI upgrades and how they enhance your ChatGPT experience.
GPT-4.5 is here! Discover its game-changing AI upgrades and how they enhance your ChatGPT experience.
Artificial IntelligenceMachine LearningDeep LearningRead more
Google DeepMind Unveils On-Device Gemini AI for Robots
Offline robot AI is here. Google DeepMind unveils a compact Gemini model running directly on robots—fast, capable, and cloud-free.
AIMachine LearningRoboticsRead more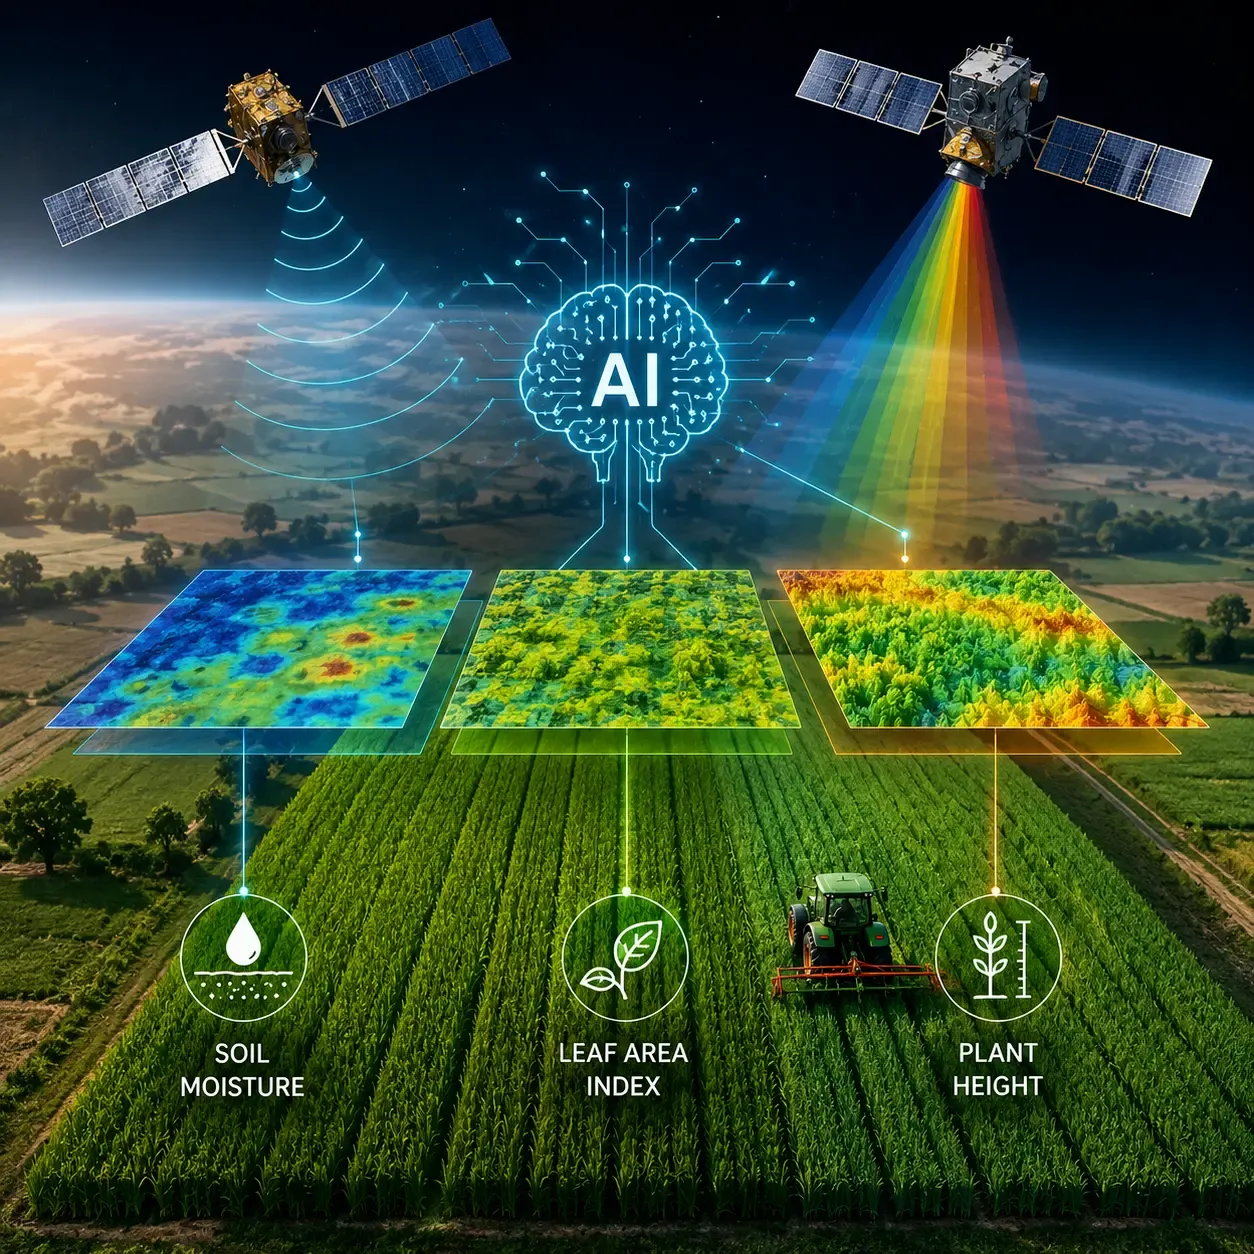
New AI Transformer Model Enhances Crop Monitoring with Satellite Data
A newly developed AI model combines radar and optical satellite imagery to improve crop monitoring accuracy, offering new possibilities for precision agriculture and data-driven farm management.
Artificial IntelligenceMachine LearningPrecision AgricultureRead more
Get Ready for GPT-5: What’s Coming in August
OpenAI is preparing to release GPT-5 in early August, promising smarter, more efficient reasoning and multimodal capabilities.
Artificial IntelligenceDeep LearningOpenAIRead more
Comments
Be the first to share your thoughts
No comments yet
Start the conversation by sharing your thoughts